Day 4 · The Shape of a Sign
A letter is not one shape but a range of shapes. No two scribes draw it the same way. In fact, no writer ever writes a letter the exact same way twice. Today you’ll measure how close those shapes are to one another.
What paleography is
Paleography is the study of old handwriting: how letters were formed, how that forming changed over time and from place to place, and what those changes let us infer about a manuscript. The word comes from the Greek for “ancient writing.” It is one of the oldest skills in our field and still one of the least automated.
A trained paleographer can look at a page and do several things at once, often without being able to say exactly how:
Date a hand. The way letters are shaped drifts steadily over the centuries. A scribe trained in 1100 does not write like one trained in 1400. An experienced eye can often place an undated hand to within fifty years from the shapes alone.
Localize it. Scripts cluster by region and by institution. A particular way of finishing a stroke, a particular abbreviation, can point to a part of Europe, a single monastery, or a single chancery.
Identify scribes. Within a manuscript, or across several, a paleographer can sometimes tell that two stretches of writing came from the same hand, or that an apparent single hand is really two. This is how Hengwrt and Ellesmere, the two best Canterbury Tales manuscripts, were attributed to the same scribe.
Read damaged letters. When ink has flaked or a page is torn, knowing the full range of shapes a scribe used lets you reconstruct what a half-present letter must have been.
The catch is that this expertise is real but hard to scale and hard to make explicit. A paleographer who has read ten thousand pages carries that experience as trained intuition. They can be right and unable to fully spell out the rule they used, which makes the skill slow to teach and slow to apply across the thousands of manuscripts a large question would need. Their methods are impossible to replicate by any other scholar, limiting material for deep discussion, and making the entire enterprise fundamental not scientific. That gap, between a reliable judgment and a statable, repeatable procedure, is exactly the gap that measuring shapes tries to narrow.
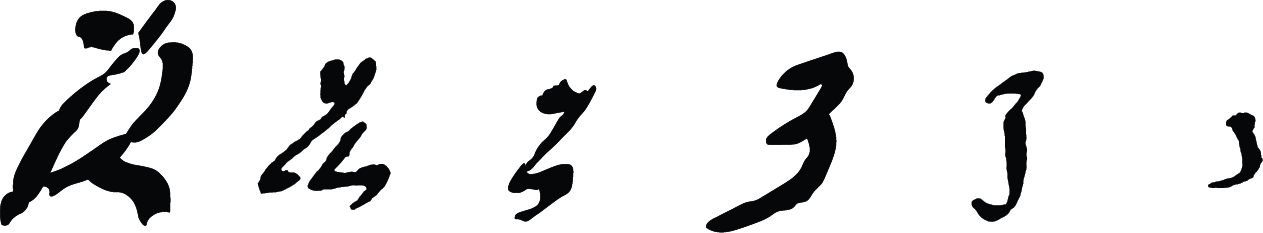
Figure 1:The evolution of hieratic 𓅓 (G17).
Discussion questions
A paleographer dates a hand to “the second quarter of the fourteenth century” and is usually right. What kind of evidence is that judgment built on, and why is it hard to write down as a rule?
Dating, localizing, and identifying a scribe are three different tasks. Which do you think is hardest from the shapes alone, and why?
If an expert can be confident without being able to explain the basis fully, what would it take to trust a measurement that disagrees with them?
What questions about your own material would you answer if you could compare the handwriting in thousands of manuscripts at once?
Graph, grapheme, allograph
Write the letter “a” five times, quickly. The five are not identical. To talk about that precisely we need three words.
A grapheme is the abstract letter: the idea of “a,” the thing all five marks have in common. It has no single shape. It is an abstract entity in the script system.
A graph is one inked instance: a particular “a” written at a particular moment by a particular hand. Every one is slightly different.
An allograph is a recognized variant form of a grapheme. Lowercase “a” and the older single-story “ɑ” are two allographs of the same letter. Roman and italic are allographs. A scribe may use one allograph at the start of a word and another in the middle.
The same grapheme appears as very different graphs from one hand to the next, and that variation is measurable. It can indicate period, scribe, or genre.
Two more terms describe how a sign is made, and they matter because two letters can look alike on the page but be built differently:
Ductus is the path of the pen: the order, direction, and number of strokes used to form a letter. You cannot always see ductus in a finished letter, but a scribe’s habitual ductus is one of the most personal things about a hand. A modern “4” written as one stroke and a “4” written as two can look identical when dry.
Letterform morphology is the finished geometry of the sign: its proportions, the angle of its strokes, where it has corners and where it has curves, whether it has serifs or feet.
What varies across hands, periods, and genres is exactly this: which allographs a scribe favors, the ductus behind them, and the morphology that results. A formal liturgical book and a hasty personal letter, written the same year by the same person, can use noticeably different forms of the same grapheme. Genre changes the hand.
Discussion questions
If a letter can be drawn in countless ways, what makes two marks the same grapheme? Where is the boundary between “a different graph” and “a different letter”?
Scribal variation is usually treated as noise. When might it be the signal you are after?
Ductus often can’t be seen in the dried ink, yet it’s one of the most diagnostic things about a hand. What would let you recover it?
A scribe uses formal letterforms in a Bible and looser ones in a note. Is that the “same hand”? What would you have to hold constant to compare two hands fairly?
Digitizing is the hard part
Before a sign can be measured it has to be turned into data a computer can work on. That happens in three steps, and the difficulty is concentrated in the last one.
Imaging. Someone photographs the page. This sounds trivial and is not: resolution, lighting, and color all affect everything downstream. A sign photographed at low resolution simply has fewer pixels to measure. Special techniques (raking light, multispectral imaging) can recover ink that the naked eye misses, which is why digitization is often where faded or palimpsested text is first read at all.
Binarization. The image is reduced to ink versus background: usually black ink on white, every pixel sorted into one or the other. This is what separates the writing from the parchment, stains, show-through from the other side of the leaf, and ruling lines. On a clean page a simple brightness threshold works. On a dark, damaged, or unevenly lit page it does not, and a bad binarization quietly throws away strokes or invents them.
Segmentation. The page is cut into individual signs, one crop per sign, so each can be measured on its own. This is the genuinely hard part. Signs touch, overlap, and break. A ligature joins two letters with a single stroke. A descender from the line above dips into the line below. A cracked letter falls into two pieces. Deciding where one sign ends and the next begins is often genuinely unclear, and there is no clean page-independent rule that gets it right.
Segmentation matters out of proportion to its glamour because segmentation errors propagate into every later measurement. If you crop two touching letters as one sign, every number you compute for that “sign” is measuring a thing that does not exist. Get the cutting wrong and nothing downstream can recover.
This is also why automatic handwriting recognition handles clean printed Latin script well and damaged, variable, non-Latin scripts poorly, which is exactly the material this kind of work involves. Printed type is regularly spaced and uniform, so segmentation is easy and the shapes are consistent. The manuscripts we care about are none of those things.
Discussion questions
Imaging, binarization, segmentation. Walk through what could go wrong at each step with a water-damaged page, and which error would be hardest to notice later.
Why is segmentation harder for handwriting than for printed type? Name two specific things a scribe does that a printing press doesn’t.
“Segmentation errors propagate.” Give a concrete example: you crop two touching letters as one. What does that do to a similarity score later?
Multispectral imaging can recover ink the eye can’t see. Does that change which manuscripts are worth measuring at all?
From a shape to numbers
To compare two signs by computer, each has to become a list of numbers, a feature vector. A feature vector is just a row of measurements describing one thing, so that two things can be compared by comparing their rows. There are three broad ways to choose those numbers, from crudest to most sophisticated.
Raw pixels. Take the cropped, binarized sign, lay its pixels out in a fixed order, and read off the brightness of each. A 16×16 crop becomes 256 numbers. This is the simplest possible feature vector and the one the notebook starts with. It is easy and it works for a demonstration, but it is fragile: it treats the sign as a grid of dots with no idea that those dots form strokes, and it is extremely sensitive to position, size, and rotation.
Engineered features. Instead of raw pixels, measure things a paleographer might actually name: the height-to-width proportion, the number of strokes, the slant angle, how much ink sits in the top half versus the bottom, the curvature of the contour, statistical moments that summarize the overall distribution of ink. These are fewer numbers and more meaningful ones. They are designed by hand to capture what matters and ignore what doesn’t, so they tend to be steadier than raw pixels.
Learned features. A neural network can be trained to invent its own features from many labeled examples, finding the measurements that best separate the signs it was shown. These often outperform hand-designed features, but they need a lot of training data and they are harder to interpret. You get numbers that work without an easy account of what each one means.
Whatever the features, one step comes first: normalization. Pixel features are sensitive to rotation and size, so we normalize before comparing. If one scribe’s “a” is twice as tall, or sits in the corner of its crop, or leans ten degrees more, a raw comparison will call two identical shapes different, not because the shapes differ but because the framing does. Normalizing means centering each sign, scaling it to a standard size, and, where appropriate, correcting its rotation, so that the comparison is about shape and not about accidents of cropping. The notebook shows a normalization step lifting similarity scores between signs that were always the “same” shape.
Discussion questions
Raw pixels know nothing about strokes. They’re just a grid of dots. Name one pair of signs that pixels would confuse and a human never would.
If you were designing engineered features for your script, what three measurements would you start with, and what would each one capture?
Learned features often work better but are harder to explain. When does it matter that you can’t say what a feature means, and when doesn’t it?
Why must normalization come before comparison? What real scribal difference might you accidentally erase by normalizing too aggressively, say, by correcting slant?
Similarity and distance
Once every sign is a feature vector, comparing two signs means comparing two rows of numbers. There are two standard ways to put a number on how alike they are.
Euclidean distance is ordinary straight-line distance: treat each vector as a point and measure the gap between the points. Small distance means similar. It cares about magnitude. Two signs that differ mainly in how much ink they have will be far apart even if their shapes match.
Cosine similarity measures the angle between two vectors, ignoring their length. It runs from 0 (nothing in common) to 1 (identical direction). It cares about the pattern of ink rather than the total amount, which is often what you want for shapes, and it is less thrown off by overall darkness or thickness.
The two can disagree, and which you choose changes the answer. The notebook computes both and shows where they diverge.
With a similarity (or distance) for every pair, a few standard moves follow:
Nearest neighbors. For a chosen sign, rank all the others and take the closest few. This is the core operation behind a “find me signs that look like this one” tool.
Clustering. Group the signs so that members of a group are more like each other than like outsiders, without giving the computer any labels. If the groups it finds line up with archetypes, scribes, or periods, the features are capturing something real.
A similarity heatmap. Lay every sign along both axes of a grid and color each cell by how similar that pair is. Bright blocks along the diagonal mean each group’s members resemble each other. Bright off-diagonal patches reveal signs that look alike across groups, often exactly the confusions worth examining.
A confusion is itself informative. When two archetypes get mixed up, the heatmap shows it as a bright patch off the diagonal, and that tells you which shapes your features can’t yet tell apart. The notebook builds a small confusion example so you can see this happen.
Discussion questions
Euclidean distance cares about magnitude. Cosine similarity cares about direction. For comparing the shape of two signs, which fits better, and what would push you to the other?
Nearest neighbors gives you the closest signs to one you picked. How would you check whether “closest by number” agrees with “closest to the eye”?
Clustering uses no labels. If its groups match your scribes, what have you learned? If they cut across your scribes instead, what might that mean?
A bright off-diagonal patch on the heatmap says two different things look alike to the features. Is that a flaw to fix or a finding to keep?
HTR and the Isut Guesser
Handwritten text recognition (HTR) is the task of turning a page of handwriting into machine-readable text, the handwriting equivalent of OCR for printed books. A trained HTR model takes a manuscript image and outputs a transcription. The main tools are Transkribus and eScriptorium: you upload page images, correct a sample of transcriptions to train the model on your material, and it then transcribes the rest.
HTR does well on clean, consistent material and poorly on the hard cases. It transcribes a tidy printed Latin book or a uniform scribal hand with high accuracy. It struggles with damaged pages, highly variable hands, and non-Latin scripts, the same reasons segmentation struggles, plus a deeper one: a model only knows the shapes it was trained on, and for most historical and non-Latin scripts there is little training data. The material this field most wants to read is the material HTR finds hardest, which is why measuring shapes directly (rather than waiting for a full transcription) is often the more useful first move.
The Isut Guesser is one of those direct tools. You draw a sign and it returns the signs most similar to yours. Under the hood that is nearest-neighbors-on-shapes: your drawing becomes a feature vector, every sign in the collection is already a feature vector, and it ranks them by similarity and hands back the closest. It does not need to “read” anything or transcribe a page. Today’s notebook is a teaching-scale version of the same idea, built on made-up signs so the whole pipeline runs end to end before real images go in.
Discussion questions
HTR is best on exactly the material we care about least and worst on the material we care about most. Why does that pattern hold, and what would change it?
The Isut Guesser ranks shapes without transcribing them. When is “find me similar signs” more useful than “tell me what this says”?
Training an HTR model means correcting a sample by hand first. How much hand-correction is worth it, and how would you decide?
Explore Isut
Open Isut’s Guesser, draw a sign, and see what it returns. Then look through the sign analysis view and find a sign whose shape clearly varies across texts.
For a worked version, the notebook’s last section loads real drawings of G17 (the owl) straight from the Isut data in the repository and shows the same sign in a dozen different hands. That is today’s whole point: one sign, no two scribes drawing it alike.
Discussion questions
Draw the same sign twice, carefully and then carelessly. Do the Guesser’s results change? What does that tell you about how it measures?
Find a sign whose shape varies a lot across texts. Would you want a tool to treat those variants as one sign or as several? Why?
Measure similarity
The notebook converts each sign image into numbers and scores every pair for similarity. Pick a sign and find its nearest matches by shape. Do they agree with your eye? Where they don’t, the disagreement tells you something about what the features actually capture. Then run the normalization step and the two distance metrics, add noise and watch the nearest-neighbor results degrade, and read off which archetypes get confused.